Jev Calibration Lab
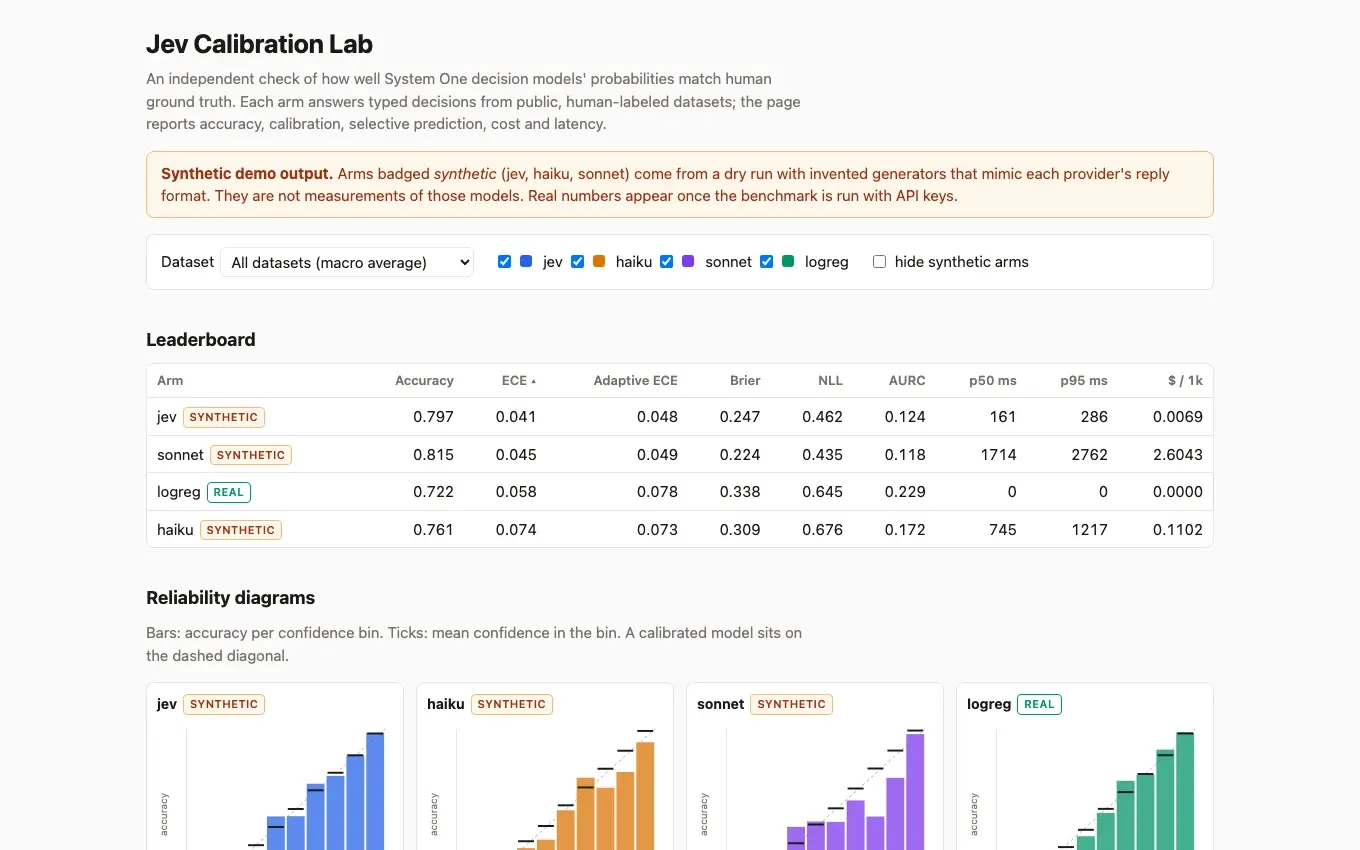
An independent benchmark that checks whether a decision model’s probabilities match human labels, against frontier LLMs and a cheap baseline.
- Role
- Solo
- Stack
Problem
TypeSafe’s Jev returns decisions with a probability attached and is trained for calibration, but its published benchmark defines ground truth as the average of two frontier LLMs. That measures agreement with those LLMs, not whether a 0.8 is right 80% of the time against people. I couldn’t find an independent check, so I wrote one.
What I built
Five public datasets labeled by people (SST-2, BoolQ, LIAR, banking77, SMS Spam), 300 fixed-seed evaluation items each.
One interface for every model arm: Jev, Claude Haiku and Sonnet with stated probabilities through structured output, and a TF-IDF logistic regression floor. New models are a config entry.
Metrics: accuracy, ECE and adaptive ECE, Brier, NLL, reliability diagrams, risk-coverage curves, latency, cost per 1,000 decisions, and post-hoc recalibration baselines. Results publish to a static leaderboard.
Results
- The harness is complete; real Jev and Claude runs are waiting on API keys. Their numbers on the leaderboard come from labeled synthetic generators, not from the APIs.
- Real baseline numbers: TF-IDF logistic regression reaches 0.807 accuracy on SST-2 and 0.967 on SMS Spam, and is underconfident on banking77, where temperature scaling cuts ECE from 0.119 to 0.038.